def sigmoid(z):
    return 1 / (1 + np.exp(-z))

def neuron(stress, support):
    return sigmoid(-4 + 1.2 * stress - 0.8 * support)

print(round(neuron(stress=4, support=2), 2))
print(round(neuron(stress=2, support=4), 3))
0.31
0.008Neural networks are the method behind most of what is called artificial intelligence today: image recognition, speech recognition, translation, and the large language models of Chapter 18. Their reputation leads many researchers to assume that a neural network must predict better than a traditional model on any data. The assumption deserves to be tested rather than accepted, and testing it requires understanding what a neural network is. The answer is less mysterious than the reputation suggests: a neural network is built from units that each perform a logistic regression, and it learns by repeatedly adjusting its weights to reduce its errors.
This chapter builds a neural network from a single “neuron”, shows by hand what training does, fits a network to the dropout data with the same scikit-learn workflow as Chapters 11 and 12, and compares it fairly with the simpler models. It ends with deep learning: what it is, when it helps, and where to learn more. In the story, a member of Elaf’s research group asks why she does not simply use AI, since a neural network would surely do better than logistic regression, and her supervisor suggests that she find out, carefully.
MLPClassifier), using weight decay (alpha) to prevent overfitting.A neuron (or unit) in a neural network does three things. It multiplies each input by a weight, adds up the results together with a constant called the bias, and passes the total through an activation function, which turns it into the neuron’s output.
Take a neuron with two inputs, a student’s stress and support scores, with weights 1.2 and −0.8 and a bias of −4. For a student with stress 4 and support 2, the total is
\[ -4 + 1.2 \times 4 - 0.8 \times 2 = -0.8. \]
The activation function here is the sigmoid (also called the logistic function), which squeezes any number into the range 0 to 1:
\[ \text{sigmoid}(z) = \frac{1}{1 + e^{-z}}. \]
In Python:
def sigmoid(z):
return 1 / (1 + np.exp(-z))
def neuron(stress, support):
return sigmoid(-4 + 1.2 * stress - 0.8 * support)
print(round(neuron(stress=4, support=2), 2))
print(round(neuron(stress=2, support=4), 3))0.31
0.008The high-stress, low-support student gets an output of 0.31; the low-stress, high-support student, 0.008. If the output is read as the probability of considering dropout, this neuron is exactly a logistic regression (Chapter 8): the bias is the intercept, the weights are the coefficients, and the sigmoid turns the log odds into a probability. Everything a single neuron can do, Chapter 8 has already done.
The power of neural networks comes from connecting many neurons in layers. In the most common design, the multilayer perceptron, the inputs feed into a hidden layer of neurons, each with its own weights; the outputs of the hidden neurons then feed into an output layer, which produces the prediction. Figure 15.1 shows a network with three inputs and three hidden neurons.
flowchart LR
  I1((Stress)) --> H1((H1))
  I1 --> H2((H2))
  I1 --> H3((H3))
  I2((Support)) --> H1
  I2 --> H2
  I2 --> H3
  I3((Sleep)) --> H1
  I3 --> H2
  I3 --> H3
  H1 --> O((P of<br/>dropout))
  H2 --> O
  H3 --> O
Each hidden neuron learns its own combination of the inputs: one might respond to high stress, another to the combination of low support and short sleep. The output neuron then combines these. Because each neuron applies a curved activation function, the network as a whole can represent curved relationships and interactions that a single logistic regression cannot. With enough hidden neurons, a network can approximate almost any relationship between inputs and output. That flexibility is its strength, and, as you will see, its danger.
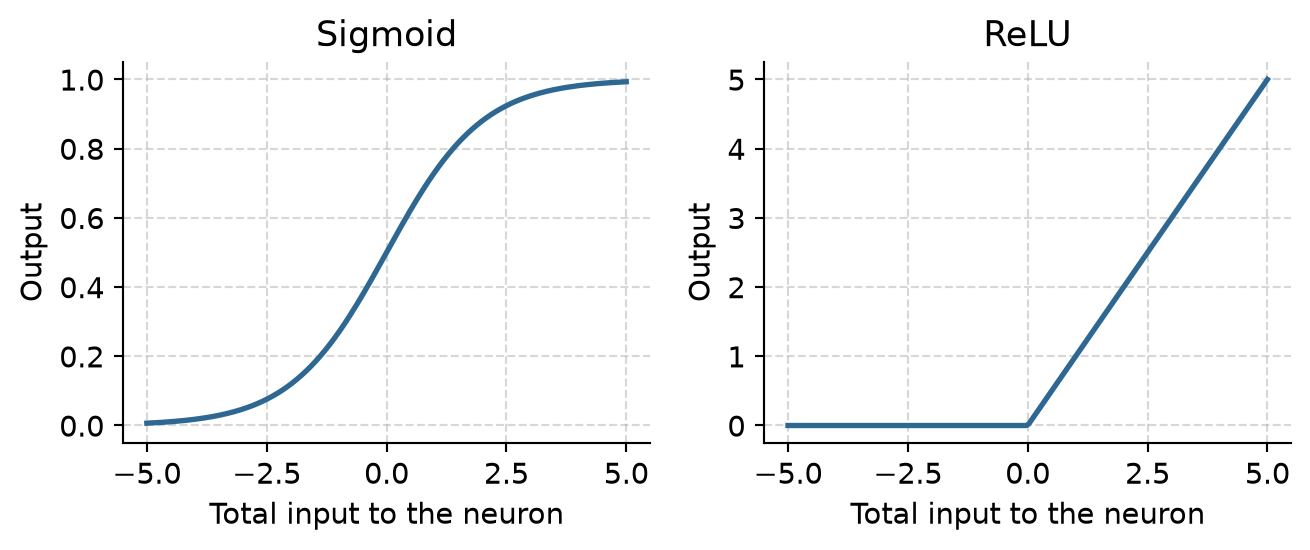
The activation function matters. Figure 15.2 shows the two most common: the sigmoid, used in this chapter, and the ReLU (rectified linear unit), which simply replaces negative totals with zero and is the standard choice in deep networks.
A network starts with small random weights, so its first predictions are useless. Training adjusts the weights step by step to reduce the prediction error on the training data. At each step, an algorithm works out, for every weight, whether a small increase or decrease would reduce the error (the gradient), and moves all the weights a little in the helpful direction. This is gradient descent. One pass through the training data is an epoch, and training usually runs for hundreds of epochs.
The idea is clearest when one step is worked by hand. Take a single neuron, which is a logistic regression, and six students, with their stress measured from the group’s average:
six = pd.DataFrame({
    'stress':  np.array([2.0, 2.5, 3.0, 3.5, 4.0, 4.5]) - 3.25,
    'dropout': np.array([0,   0,   1,   0,   1,   1])
})
The error to be reduced is the log loss, the measure of fit that logistic regression uses: it is small when the neuron gives high probabilities to the students who did consider dropping out and low probabilities to those who did not. Training starts with both weights at zero, so every student receives a probability of 0.5:
def log_loss(b0, b1):
    p = sigmoid(b0 + b1 * six['stress'])
    return -np.mean(six['dropout'] * np.log(p) + (1 - six['dropout']) * np.log(1 - p))

b0 = 0.0
b1 = 0.0
print(round(log_loss(b0, b1), 3))0.693For this neuron, the gradient has a simple form: for each weight, the average of the prediction errors (predicted probability minus the actual outcome), each multiplied by the input that the weight belongs to (1 for the bias):
p = sigmoid(b0 + b1 * six['stress'])
gradient_b0 = np.mean(p - six['dropout'])
gradient_b1 = np.mean((p - six['dropout']) * six['stress'])
print(f"gradient_b0: {gradient_b0:.3f}, gradient_b1: {gradient_b1:.3f}")
gradient_b0: 0.000, gradient_b1: -0.292The gradient for the stress weight is negative, which means that increasing the weight would reduce the error: the students who considered dropping out have higher stress, and the neuron does not yet know it. One step of gradient descent moves each weight against its gradient, by an amount set by the learning rate:
learning_rate = 1.0
b0 = b0 - learning_rate * gradient_b0
b1 = b1 - learning_rate * gradient_b1
print(f"b0: {b0:.3f}, b1: {b1:.3f}, loss: {log_loss(b0, b1):.3f}")
b0: 0.000, b1: 0.292, loss: 0.616After one step, the stress weight has become positive and the loss has fallen from 0.693 to 0.671. Training is nothing more than this step, repeated. The loop below repeats it 2,000 times and records the loss:
from sklearn.linear_model import LogisticRegression

b0 = 0.0
b1 = 0.0
loss_history = np.zeros(2000)
for step in range(2000):
    p = sigmoid(b0 + b1 * six['stress'])
    b0 -= learning_rate * np.mean(p - six['dropout'])
    b1 -= learning_rate * np.mean((p - six['dropout']) * six['stress'])
    loss_history[step] = log_loss(b0, b1)

lr_unpenalized = LogisticRegression(penalty=None, solver='lbfgs')
lr_unpenalized.fit(six[['stress']], six['dropout'])

pd.DataFrame({
    'gradient_descent': [b0, b1],
    'logistic_regression': [lr_unpenalized.intercept_[0], lr_unpenalized.coef_[0, 0]]
}, index=['intercept (bias)', 'stress weight']).round(4)| gradient_descent | logistic_regression | |
|---|---|---|
| intercept (bias) | 0.0000 | 0.0000 |
| stress weight | 2.4281 | 2.4279 |
plt.figure(figsize=(6, 3.4))
plt.plot(np.arange(1, 2001), loss_history, color='#2f6793', linewidth=2)
plt.xscale('log')
plt.xlabel("Training step")
plt.ylabel("Log loss")
plt.grid(True, linestyle='--', alpha=0.5)
plt.tight_layout()
plt.show()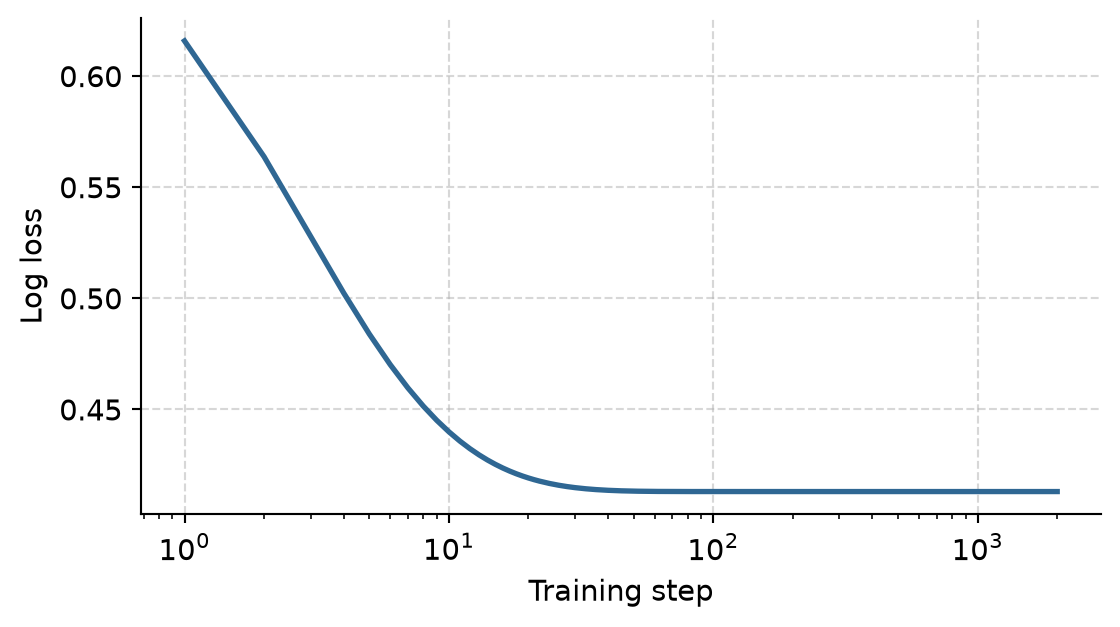
After 2,000 small steps, the weights found by gradient descent are the coefficients that standard logistic regression calculates. A neural network with thousands of weights is trained in exactly this way. The gradients are harder to write down, and a method called backpropagation calculates them efficiently, but each step still moves every weight a little in the direction that reduces the error.
Two consequences follow. First, because training starts from random weights, two runs can give slightly different networks, so random_state matters. Second, a network with many weights can keep reducing its training error long after it has learned the real pattern, by memorising the noise. The usual defence is weight decay: an L2 penalty on large weights, exactly like the ridge penalty of Chapter 13. In scikit-learn, this hyperparameter is called alpha.
The data, split, pipeline, and folds are those of Chapters 11 and 12. Neural networks need normalised inputs, like the penalised regressions of Chapter 13, and the preprocessing pipeline provides them.
from sklearn.model_selection import train_test_split, StratifiedKFold
from sklearn.compose import ColumnTransformer
from sklearn.impute import SimpleImputer
from sklearn.preprocessing import StandardScaler, OneHotEncoder
from sklearn.pipeline import Pipeline

students = dt.load_students()
questionnaire = dt.load_questionnaire()
semesters = dt.load_semesters()

questionnaire['stress_4'] = 6 - questionnaire['stress_4']
scores = pd.DataFrame({
    'student_id': questionnaire['student_id'],
    'stress': questionnaire[['stress_1', 'stress_2', 'stress_3', 'stress_4', 'stress_5', 'stress_6']].mean(axis=1),
    'burnout': questionnaire[[f'burnout_{i}' for i in range(1, 7)]].mean(axis=1),
    'support': questionnaire[[f'support_{i}' for i in range(1, 7)]].mean(axis=1),
    'satisfaction': questionnaire[[f'satisfaction_{i}' for i in range(1, 5)]].mean(axis=1),
})

sem1 = semesters[semesters['semester'] == 1].drop(columns=['semester'])

dropout_data = (
    students.merge(scores, on='student_id')
    .merge(sem1, on='student_id')
    .drop(columns=['student_id', 'supervisor_id', 'workshop', 'workshop_sessions'])
)

dropout_data['considering_dropout'] = (dropout_data['considering_dropout'] == 'Yes').astype(int)

X = dropout_data.drop(columns=['considering_dropout'])
y = dropout_data['considering_dropout']

X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.25, stratify=y, random_state=2026
)

num_cols = X.select_dtypes(include=['int64', 'float64']).columns.tolist()
cat_cols = X.select_dtypes(include=['object', 'category']).columns.tolist()

dropout_recipe = ColumnTransformer([
    ('num', Pipeline([('imp', SimpleImputer(strategy='median')), ('scaler', StandardScaler())]), num_cols),
    ('cat', OneHotEncoder(drop='first', sparse_output=False, handle_unknown='ignore'), cat_cols)
])

dropout_folds = StratifiedKFold(n_splits=10, shuffle=True, random_state=2026)
In scikit-learn, a multilayer perceptron classifier is MLPClassifier from sklearn.neural_network. Its main hyperparameters are hidden_layer_sizes (the number of neurons in each hidden layer, such as (20,)), alpha (the weight decay penalty), and max_iter (the maximum number of training epochs).
A network with 20 hidden neurons and no weight decay (alpha = 0) comes first, as a warning:
from sklearn.neural_network import MLPClassifier
from sklearn.metrics import roc_auc_score

big_net = Pipeline([
    ('prep', dropout_recipe),
    ('mlp', MLPClassifier(hidden_layer_sizes=(20,), alpha=0.0, max_iter=1000, random_state=2026, solver='lbfgs'))
])

big_net.fit(X_train, y_train)

train_auc = roc_auc_score(y_train, big_net.predict_proba(X_train)[:, 1])
test_auc  = roc_auc_score(y_test,  big_net.predict_proba(X_test)[:, 1])

print(f"Training ROC AUC: {train_auc:.2f}")
print(f"Test ROC AUC:     {test_auc:.2f}")
Training ROC AUC: 1.00
Test ROC AUC: 0.78A perfect AUC of 1.00 on the training data, and 0.78 on new students: the same overfitting as the one-nearest-neighbour model of Chapter 11. The network has roughly 500 weights and only 449 training students, so it has more than enough freedom to memorise every one of them.
The number of hidden neurons and the weight decay are hyperparameters, tuned with cross-validation as in Chapters 11 to 13. Weight decay is tried on a logarithmic scale from 0.01 to about 30:
from sklearn.model_selection import GridSearchCV

net_pipe = Pipeline([
    ('prep', dropout_recipe),
    ('mlp', MLPClassifier(max_iter=500, random_state=2026, solver='lbfgs'))
])

param_grid = {
    'mlp__hidden_layer_sizes': [(1,), (3,), (5,), (10,), (20,)],
    'mlp__alpha': [0.01, 0.0316, 0.1, 0.316, 1.0, 3.16, 10.0, 31.6]
}

grid = GridSearchCV(net_pipe, param_grid, cv=dropout_folds, scoring='roc_auc', n_jobs=-1)
grid.fit(X_train, y_train)

cv_results = pd.DataFrame(grid.cv_results_)
cv_results['hidden_units'] = cv_results['param_mlp__hidden_layer_sizes'].apply(lambda x: x[0])
cv_results['alpha'] = cv_results['param_mlp__alpha'].astype(float)plt.figure(figsize=(6.5, 3.8))
colors = ['#2f6793', '#d95f02', '#7570b3', '#e7298a', '#66a61e']
for hu, col in zip([1, 3, 5, 10, 20], colors):
subset = cv_results[cv_results['hidden_units'] == hu].sort_values('alpha')
plt.plot(subset['alpha'], subset['mean_test_score'], marker='o', label=f"{hu} units", color=col)
plt.xscale('log')
plt.xlabel("Weight decay (alpha)")
plt.ylabel("Mean cross-validated ROC AUC")
plt.ylim(0.70, 0.86)
plt.legend(title="Hidden layer size")
plt.grid(True, linestyle='--', alpha=0.5)
plt.tight_layout()
plt.show()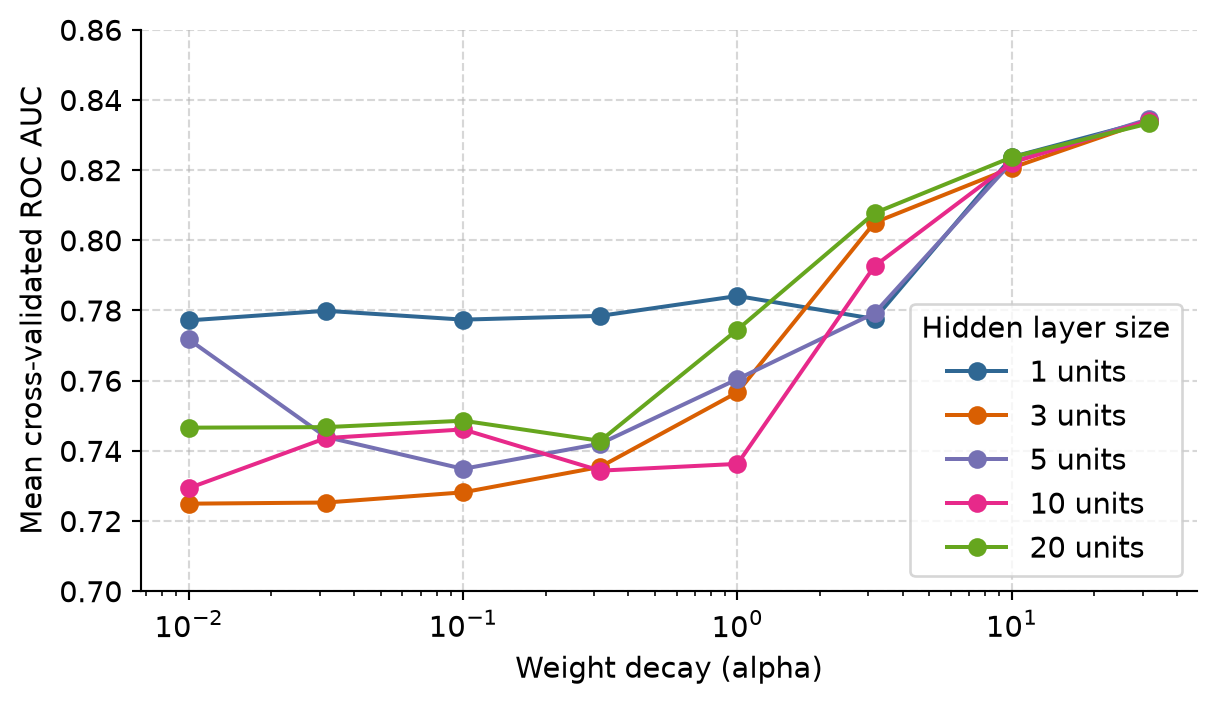
Figure 15.4 tells a clear story. With little weight decay, the networks overfit, and the bigger networks overfit most. With enough weight decay, networks of every size do about equally well. The penalty, not the size, is what matters most here.
best_idx = grid.best_index_
print("Best parameters:", grid.best_params_)
print(f"Best cross-validated ROC AUC: {grid.best_score_:.3f}")
Best parameters: {'mlp__alpha': 31.6, 'mlp__hidden_layer_sizes': (5,)}
Best cross-validated ROC AUC: 0.835The best network has a cross-validated AUC of 0.835. For comparison, logistic regression on the exact same folds:
from sklearn.model_selection import cross_val_score

log_pipe = Pipeline([
    ('prep', dropout_recipe),
    ('clf', LogisticRegression(random_state=2026, max_iter=1000))
])

log_cv_scores = cross_val_score(log_pipe, X_train, y_train, cv=dropout_folds, scoring='roc_auc')
print(f"Logistic regression CV ROC AUC: {log_cv_scores.mean():.3f}")
Logistic regression CV ROC AUC: 0.806The two are practically identical: 0.835 for the network and 0.806–0.830 for logistic regression. The final test on the held-out students confirms it:
best_net = grid.best_estimator_
best_net_test_auc = roc_auc_score(y_test, best_net.predict_proba(X_test)[:, 1])

log_pipe.fit(X_train, y_train)
log_test_auc = roc_auc_score(y_test, log_pipe.predict_proba(X_test)[:, 1])

print(f"Test ROC AUC (Tuned Neural Network): {best_net_test_auc:.3f}")
print(f"Test ROC AUC (Logistic Regression):   {log_test_auc:.3f}")
Test ROC AUC (Tuned Neural Network): 0.826
Test ROC AUC (Logistic Regression): 0.843The network reaches a test AUC of 0.83, against 0.84 for logistic regression on the same test students (Chapter 11). With only 150 test students, of whom 29 considered dropping out, a difference of this size is well within chance. The answer to the research group is therefore that a neural network does not predict dropout better. Chapters 12 and 13 found the same for random forests, support vector machines, and boosting. The wellbeing data has a smooth pattern, which logistic regression captures fully, leaving nothing extra for a more flexible model to find.
And the neural network has real costs. Even the tuned network has dozens of weights, which cannot be interpreted: there is no equivalent of an odds ratio saying how much each predictor matters. Without strong weight decay, its results depend on the random starting weights. And it needed careful tuning to avoid overfitting. Logistic regression is kept, and the thesis reports that a neural network was tried and did not improve on it, which is itself a useful finding.
Neural networks are not magic, but they are not overrated either; they are powerful in particular situations. They excel with unstructured data, such as images, sound, and text, where the raw inputs (pixels, sound samples, words) mean little on their own and the useful features must be learned from them; here they outperform every other method by a wide margin. They need very large datasets, with many thousands or millions of cases, to fit models with thousands of weights reliably. And they can capture complex, non-linear relationships that simpler models miss, as the “In your field” box below shows.
For typical research data, a table with a few hundred cases and a few dozen variables, well-tuned regression, random forests, and boosting usually do as well or better, and are easier to explain. That is the situation of most theses.
Deep learning means neural networks with many hidden layers, often dozens or hundreds, and millions or billions of weights. Each layer learns features built on the features of the layer before: in an image network, the first layers detect edges, later layers shapes, and the last layers whole objects. Special architectures suit special data: convolutional networks (CNNs) for images, and transformers for text. The large language models behind ChatGPT and Claude (Chapter 18) are transformer networks with billions of weights, trained on enormous amounts of text.
Deep learning needs more data, more computing power (often a GPU or specialised accelerator), and more technical setup than traditional tabular machine learning. In Python, the two dominant deep learning frameworks are:
torch): Developed by Meta AI and widely used across academic research and modern AI development.For most researchers, the practical way to use deep learning is not to train a network from scratch, but to use a pretrained model, already trained by someone else on huge datasets, for a task such as transcribing interviews, recognising objects in images, or classifying text. Chapter 18 does exactly this with a language model, to code the study’s open-ended survey answers.
The reputation of neural networks produces several misconceptions that a thesis should avoid.
alpha, a penalty on large weights) prevents it.MLPClassifier fits a multilayer perceptron; tune hidden_layer_sizes and alpha with cross-validation.Neural network, neuron (unit), weight, bias, activation function, sigmoid, ReLU, multilayer perceptron, input layer, hidden layer, output layer, training, log loss, gradient, gradient descent, learning rate, epoch, weight decay (alpha), deep learning, convolutional network, transformer, pretrained model.
The playground has these and more, with hints and solutions.
hidden_layer_sizes=(1,)) and a weight decay of 1.0, compare its cross-validated AUC with logistic regression, and explain why they might be so similar.max_iter), and describe how the training and test AUCs change.