flowchart LR
  A["report.qmd<br>text + code"] --> B["Jupyter runs<br>the Python code"] --> C["report.md<br>text + results"] --> D["Pandoc"]
  D --> E[HTML]
  D --> F[Word (.docx)]
  D --> G[PDF]
Reproducible Research
Reproducible Research
A finding is credible only if it can be checked
Chapter 17
Polla Fattah
By the end of today you can
- explain why reproducibility is a matter of research integrity;
- write a Quarto document with text, Python code, dynamic results, tables, figures, citations, and equations;
- render it to HTML, Word, and PDF;
- keep package versions with virtual environments and
requirements.txt, and report them; - build a small Shiny for Python dashboard;
- apply open science practices: sharing, protecting participants, preregistering, citing software.
Three weeks before the deadline
Twelve duplicated students are found in an early version of the survey export.
They were removed in Chapter 3, but some tables were copied into the draft before that.
Now every number copied by hand from Python into Word must be checked and replaced, one at a time.
Reproducible and replicable
| Term | Means |
|---|---|
| reproducible | same data and code give exactly the same results |
| replicable | a new study with new data reaches the same conclusions |
Reproducibility is the minimum standard: if results cannot be recomputed, asking whether they replicate is pointless.
Most irreproducibility is everyday friction
- a table copied before the data was corrected;
- a spreadsheet cell edited by hand;
- menu clicks nobody wrote down;
- a package that changed its default.
Habits from earlier chapters already guard against much of this.
Habits you already have
| Habit | Chapter |
|---|---|
| every step written as code in Python | 1 |
| a dedicated project directory with relative paths | 1 |
| raw data never edited by hand | 3 |
np.random.seed() before random steps |
7 |
Today adds the last links: results placed into the report automatically, fixed software versions, and responsible sharing.
Documents that contain their own analysis
Quarto documents (.qmd) mix text and code.
When rendered, the code runs and its numbers, tables, and figures are placed into a web page, Word document, PDF, slide show, or book.
This course’s book and these slides are written in Quarto. Jupyter Notebooks (.ipynb) are popular for exploration, but Quarto plain text is vastly cleaner for Git and reproducible reports.
A complete Quarto document
The three parts
| Part | Where | Holds |
|---|---|---|
| YAML header | between the --- lines |
title, author, output format, Python kernel |
| Markdown text | the body | **bold**, *italic*, # Heading, - bullets |
| code chunks | between {python} and ``` |
Python code run when rendering |
In VS Code or Positron: click Render or run quarto render report.qmd.
Inline code: numbers never typed by hand
Inline expressions inside a sentence are evaluated and replaced by their result:
The sample included 600 graduate students from 5 faculties.
If a student is added or removed, the sentence changes with the data.
This is the permanent cure for the problem three weeks before the deadline.
What happens when you render
The code runs from the beginning every time. Anything created by hand in an interactive terminal makes rendering fail: a built-in reproducibility test.
A results chapter in Quarto
---
title: "Chapter 4: Results"
format: docx
jupyter: python3
bibliography: references.bib
execute:
  echo: false
---

```{python}
#| label: setup
#| message: false
import pandas as pd
import data2thesis as dt
students = dt.students
semesters = dt.semesters
```

The sample included 600 graduate students from 5 faculties. Table @tbl-faculty
shows wellbeing by faculty, which declined as in earlier studies [@author2020].
format: docx gives the Word file supervisors want; echo: false hides the code but keeps it in the .qmd.
A numbered table from code
```{python}
#| label: tbl-faculty
#| tbl-cap: "Wellbeing in the first semester, by faculty."
merged = semesters[semesters['semester'] == 1].merge(students, on='student_id')
summary = (
    merged.groupby('faculty')
    .agg(Students=('student_id', 'count'),
         Mean=('wellbeing', 'mean'),
         SD=('wellbeing', 'std'))
    .reset_index().round(1)
)
summary
```
Chunk options start with #|. A tbl- or fig- label makes a numbered, cross-referenced item.
What the reader sees
The sample included 600 graduate students from 5 faculties. Table 1 shows wellbeing by faculty.
| Faculty | Students | Mean | SD | |
|---|---|---|---|---|
| 0 | Education | 148 | 61.9 | 13.2 |
| 1 | Health Sciences | 154 | 59.0 | 11.6 |
| 2 | Humanities | 95 | 61.7 | 11.7 |
| 3 | Natural Sciences | 87 | 61.3 | 10.5 |
| 4 | Social Sciences | 116 | 58.9 | 12.1 |
References and citations
@book{wickham2023,
  author    = {Wickham, Hadley and Çetinkaya-Rundel, Mine and Grolemund, Garrett},
  title     = {R for Data Science},
  publisher = {O'Reilly Media},
  year      = {2023}
}
[@wickham2023] in the text becomes a formatted citation, and the reference list is added.
Zotero, Mendeley, and EndNote export BibTeX. A csl: line switches between APA, Vancouver, Harvard, and thousands more.
Equations
\[ \text{logit}(p) = \beta_0 + \beta_1 \times \text{stress} + \beta_2 \times \text{support} \]
LaTeX notation, between dollar signs. Renders identically in HTML, Word, and PDF.
One line changes the output
| Format | YAML | Notes |
|---|---|---|
| web page | format: html |
interactive; for sharing online |
| Word | format: docx |
for comments; reference-doc: applies university styles |
format: pdf or format: typst |
run quarto install tinytex or use fast Typst |
|
| slides | format: revealjs |
for presentations |
A whole thesis can be a Quarto book, one .qmd per chapter.
Parameterised reports
---
title: "Wellbeing report"
format: html
jupyter: python3
params:
  faculty: "Education"
---

```{python}
faculty_data = semesters.merge(students, on='student_id')
faculty_data = faculty_data[faculty_data['faculty'] == params['faculty']]
```

This report describes the students of the Faculty of Education.One report, five deans, five versions.
Packages change
A default changes, or a function disappears, and an analysis that runs today may fail, or give different results, in two years.
# 1. Create a virtual environment
python -m venv .venv

# 2. Freeze installed package versions
pip freeze > requirements.txt

# 3. Later or on another computer: restore exact versions
pip install -r requirements.txt
requirements.txt lists every package and version. Share it with your code.
Report software versions
import sys, statsmodels, sklearn, pandas
print(f"Python: {sys.version.split()[0]}")
print(f"pandas: {pandas.__version__}")
print(f"statsmodels: {statsmodels.__version__}")
Name the versions of Python and key analysis packages in the thesis methods section.
Shiny: let readers ask their own questions
A report answers its author’s questions. Readers want “What about my faculty?”
| Idea | In Shiny for Python |
|---|---|
| inputs | ui.input_select(), ui.input_radio_buttons(), sliders |
| outputs | ui.output_plot(), ui.output_table() |
user interface (ui) |
where inputs and outputs appear (ui.page_sidebar()) |
| server | Python code that computes outputs from inputs |
Reactivity
flowchart LR
  F["Input:<br>faculty"] --> S["@reactive.calc<br>selected() data"]
  S --> P["Output:<br>trend plot"]
  S --> T["Output:<br>summary table"]
  M["Input:<br>measure"] --> P
  M --> T
When an input changes, Shiny reruns only what depends on it.
The dashboard: layout
from shiny import App, render, ui, reactive
import pandas as pd

app_ui = ui.page_sidebar(
    ui.sidebar(
        ui.input_select("faculty", "Faculty", choices=faculties),
        ui.input_radio_buttons("measure", "Measure", choices=measures)
    ),
    ui.card(ui.output_plot("trend")),
    ui.card(ui.output_table("summary")),
    title="Graduate Student Wellbeing"
)
The dashboard: server
def server(input, output, session):
    @reactive.calc
    def selected():
        return wellbeing_data[wellbeing_data["faculty"] == input.faculty()]

    @render.plot
    def trend():
        df = selected()
        meas = input.measure()
        fig, ax = plt.subplots(figsize=(6.5, 3.8))
        sns.lineplot(data=df, x="semester", y=meas, hue="study_mode", ax=ax)
        return fig

app = App(app_ui, server)
@reactive.calc refilters only when the faculty changes.
What the dashboard draws
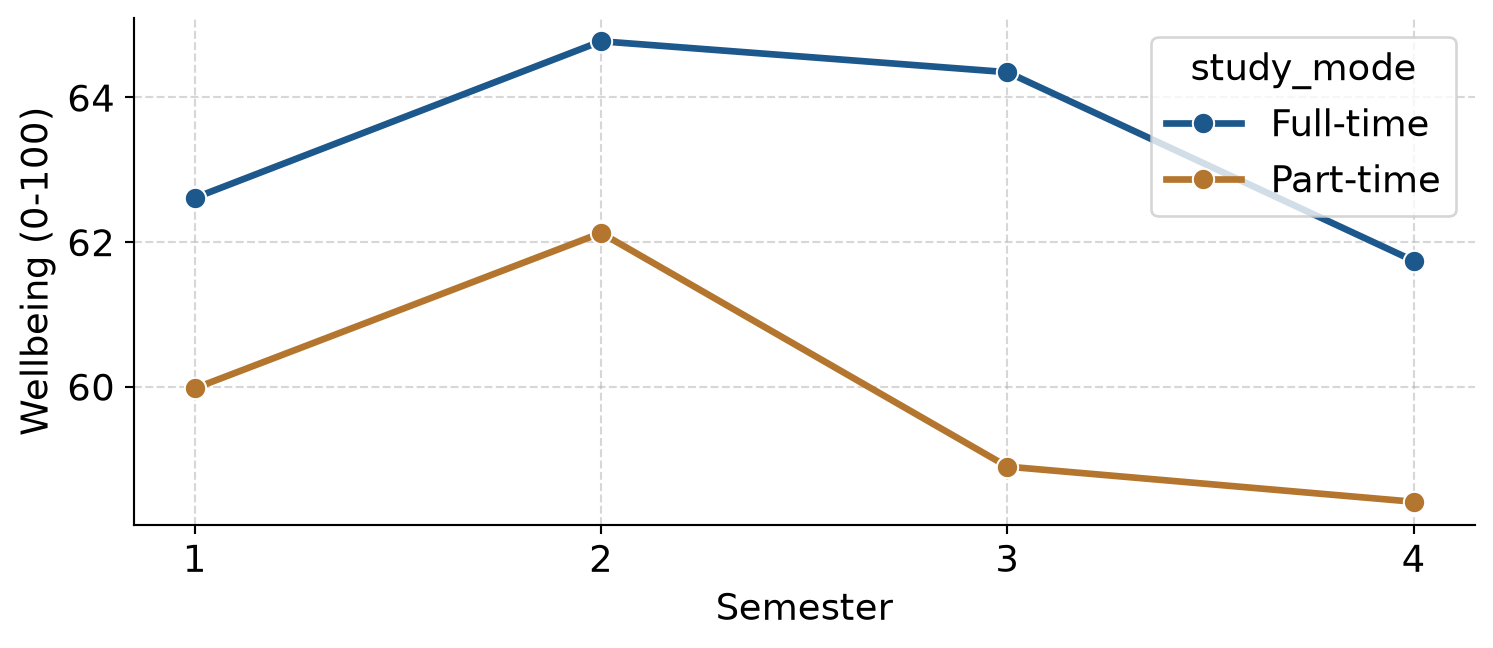
Education, wellbeing. Host on shinyapps.io or Posit Connect; Shinylive runs Python apps entirely in the browser.
Open science: sharing data and code
| Include | Why |
|---|---|
| raw data, or how to obtain it | the starting point |
| cleaning and analysis code | every step |
| the Quarto source | the report itself |
requirements.txt / uv.lock |
the software versions |
| a codebook | what each variable means |
OSF and Zenodo give a permanent DOI. A licence (CC BY for data, MIT for code) states what others may do.
Removing names is not enough
| faculty | study_mode | gender | has_children | n | |
|---|---|---|---|---|---|
| 7 | Education | Part-time | Male | Yes | 3 |
| 15 | Health Sciences | Part-time | Male | Yes | 3 |
| 21 | Humanities | Part-time | Female | Yes | 3 |
| 5 | Education | Part-time | Female | Yes | 4 |
Only 3 students are part-time male students with children in Education.
In a small department, such a description points to recognisable individuals.
Protecting participants
- group categories or remove unneeded variables;
- share summary data only;
- follow the consent form: if it promised anonymised data, that is all;
- when data cannot be shared, a synthetic dataset lets others run the code.
The garden of forking paths
# Five defensible analyses of the exact same data:
# 1. Standard t-test
# 2. Outliers trimmed (|z| < 2)
# 3. Log-scale t-test
# 4. Mann-Whitney U rank test
# 5. Linear model with covariate
No real group difference. Five defensible analyses, 1,000 simulated studies.
Choosing afterwards inflates false positives
| Analysis strategy | False positives |
|---|---|
| one planned analysis | ~5% |
| best of five, chosen afterwards | ~11% |
| best of ten, chosen afterwards | ~14% |
No individual choice is wrong. The problem is choosing after seeing the result.
Preregistration
- record hypotheses, design, and planned analysis before seeing the data;
- in a time-stamped registry: OSF Registries or AsPredicted;
- confirmatory analyses follow the plan; exploratory ones are labelled as such;
- a registered report is accepted before data collection, whatever the results.
Citing software
“Analyses were carried out in Python version 3.13 (Python Software Foundation), with data manipulation in pandas (McKinney, 2010), statistical tests in SciPy (Virtanen et al., 2020), and regression in statsmodels (Seabold & Perktold, 2010).”
Open-source package developers are researchers who depend on being cited.
In your field: psychology and medicine
In 2015, 100 psychology studies were repeated.
| Originals | Replications | |
|---|---|---|
| significant results | 97% | 36% |
| average effect size | full | about half |
Small samples, flexible analyses, and selective publication. The response: preregistration, registered reports, and sharing. Medicine has required trial registration since 2005.
Keeping a history with git (optional)
| Term | Means |
|---|---|
| repository | a project folder whose history Git tracks |
| commit | a saved snapshot with a descriptive message |
| push | copy commits to GitHub, also a backup |
| pull | bring down changes made elsewhere |
Code editors (VS Code, Positron) have visual Git buttons. List private data in .gitignore.
Practical lab: the Chapter 17 playground
Work through the playground exercises in your browser, with hints and solutions.
The Quarto and Shiny for Python exercises run from the downloadable project (chapter17.zip).
Practical exercises 1–3: Quarto
- Render the tiny document, change a value, and round with inline code.
- Turn an earlier analysis into a report with a numbered table and figure.
- Add references, cite them, and switch the citation style.
Practical exercises 4–6: Shiny and open science
- Add a slider for the semesters shown in the dashboard.
- Which variable would you remove or group before sharing, and why?
- Add a sixth analysis to
forking_paths(): what happens to false positives?
Try this yourself
Take one results paragraph from your own thesis draft:
- find every number typed by hand;
- replace each with dynamic inline code;
- give each table and figure a label and a cross-reference;
- render to Word, change the data, and render again.
Troubleshooting guide (Part 1)
| Symptom | Likely cause |
|---|---|
| rendering fails, terminal works | code relies on an object made interactively |
| a number in the text is out of date | typed by hand instead of dynamic code |
| “Table ??” in the output | label lacks the tbl- prefix |
| PDF will not render | LaTeX missing; quarto install tinytex or use format: typst |
Troubleshooting guide (Part 2)
| Symptom | Likely cause |
|---|---|
| different results on another computer | package versions differ; use requirements.txt |
| a Shiny output never updates | it does not consume the reactive data |
| shared data identifies people | small cells not protected |
| a “significant” result after many tries | forking paths; preregister |
Completion checklist
Misconceptions to leave behind (Part 1)
| Misconception | Better mental model |
|---|---|
| reproducibility means sharing code | every step, decision, and version |
| copying a few numbers is harmless | the most common way a thesis drifts |
Misconceptions to leave behind (Part 2)
| Misconception | Better mental model |
|---|---|
| defensible choices give sound results | choosing afterwards inflates false positives |
| removing names makes data anonymous | combinations can identify people |
The chapter in one sentence
Keep text, code, and results together so the whole report rebuilds from the raw data with one command, and share it in a way others can check and participants can trust.
Next: Chapter 18
The next chapter looks at AI and Natural Language Processing in research:
- coding open-ended responses with AI;
- inter-rater reliability (Cohen’s kappa);
- text embeddings and semantic similarity;
- prompt engineering and LLMs as research assistants;
- responsible AI disclosure in academic thesis work.
Questions
How many numbers in your current draft were typed by hand?
What would it take to rebuild your results from the raw data tomorrow?