Introduction to Machine Learning in Python
Introduction to Machine Learning in Python
Judged by one thing: how well it works on new cases
Chapter 11
Polla Fattah
By the end of today you can
- tell supervised from unsupervised learning, and prediction from explanation;
- explain generalisation, overfitting, and the bias-variance trade-off;
- split data into training and test sets, and say why;
- prepare data with
ColumnTransformer, and combine it with a model in aPipeline; - evaluate a classifier, and explain why accuracy can mislead;
- use cross-validation, tune hyperparameters with
GridSearchCV, and run a final test.
Some questions are about what will happen
- which patients are likely to be readmitted?
- which loans are likely to fail?
- which students are likely to struggle, early enough to help?
The university wants to identify at-risk students at the end of their first semester.
Kinds of machine learning
| Kind | Data | Examples |
|---|---|---|
| supervised: classification | outcome is a category | considering dropout: yes or no |
| supervised: regression | outcome is a number | next semester’s GPA |
| unsupervised | no outcome; find structure | clustering (Chapters 9, 14) |
Many methods are familiar statistics: logistic regression is also a classifier.
Explanation and prediction
| Explanation (Chapters 7–10) | Prediction (Chapters 11–16) | |
|---|---|---|
| question | why does it happen? | what will happen for a new case? |
| judged by | sensible, well-estimated effects | accuracy on new data |
| typical models | simple, interpretable | anything that predicts well |
| main danger | confounding | overfitting |
A good predictor need not be a cause; a good explanation may predict poorly.
Generalisation
Any dataset holds two things:
- the pattern that would appear again in new data;
- the noise that belongs to this sample only.
A model that learns the pattern generalises. One that also learns the noise overfits.
Simulating overfitting
true_curve = lambda x: np.sin(2 * x)
# 15 noisy points from a wave
train_points = make_points(15)
new_points = make_points(300)

# Polynomial models of degree 1, 3, and 12
model_d = make_pipeline(PolynomialFeatures(d), LinearRegression())
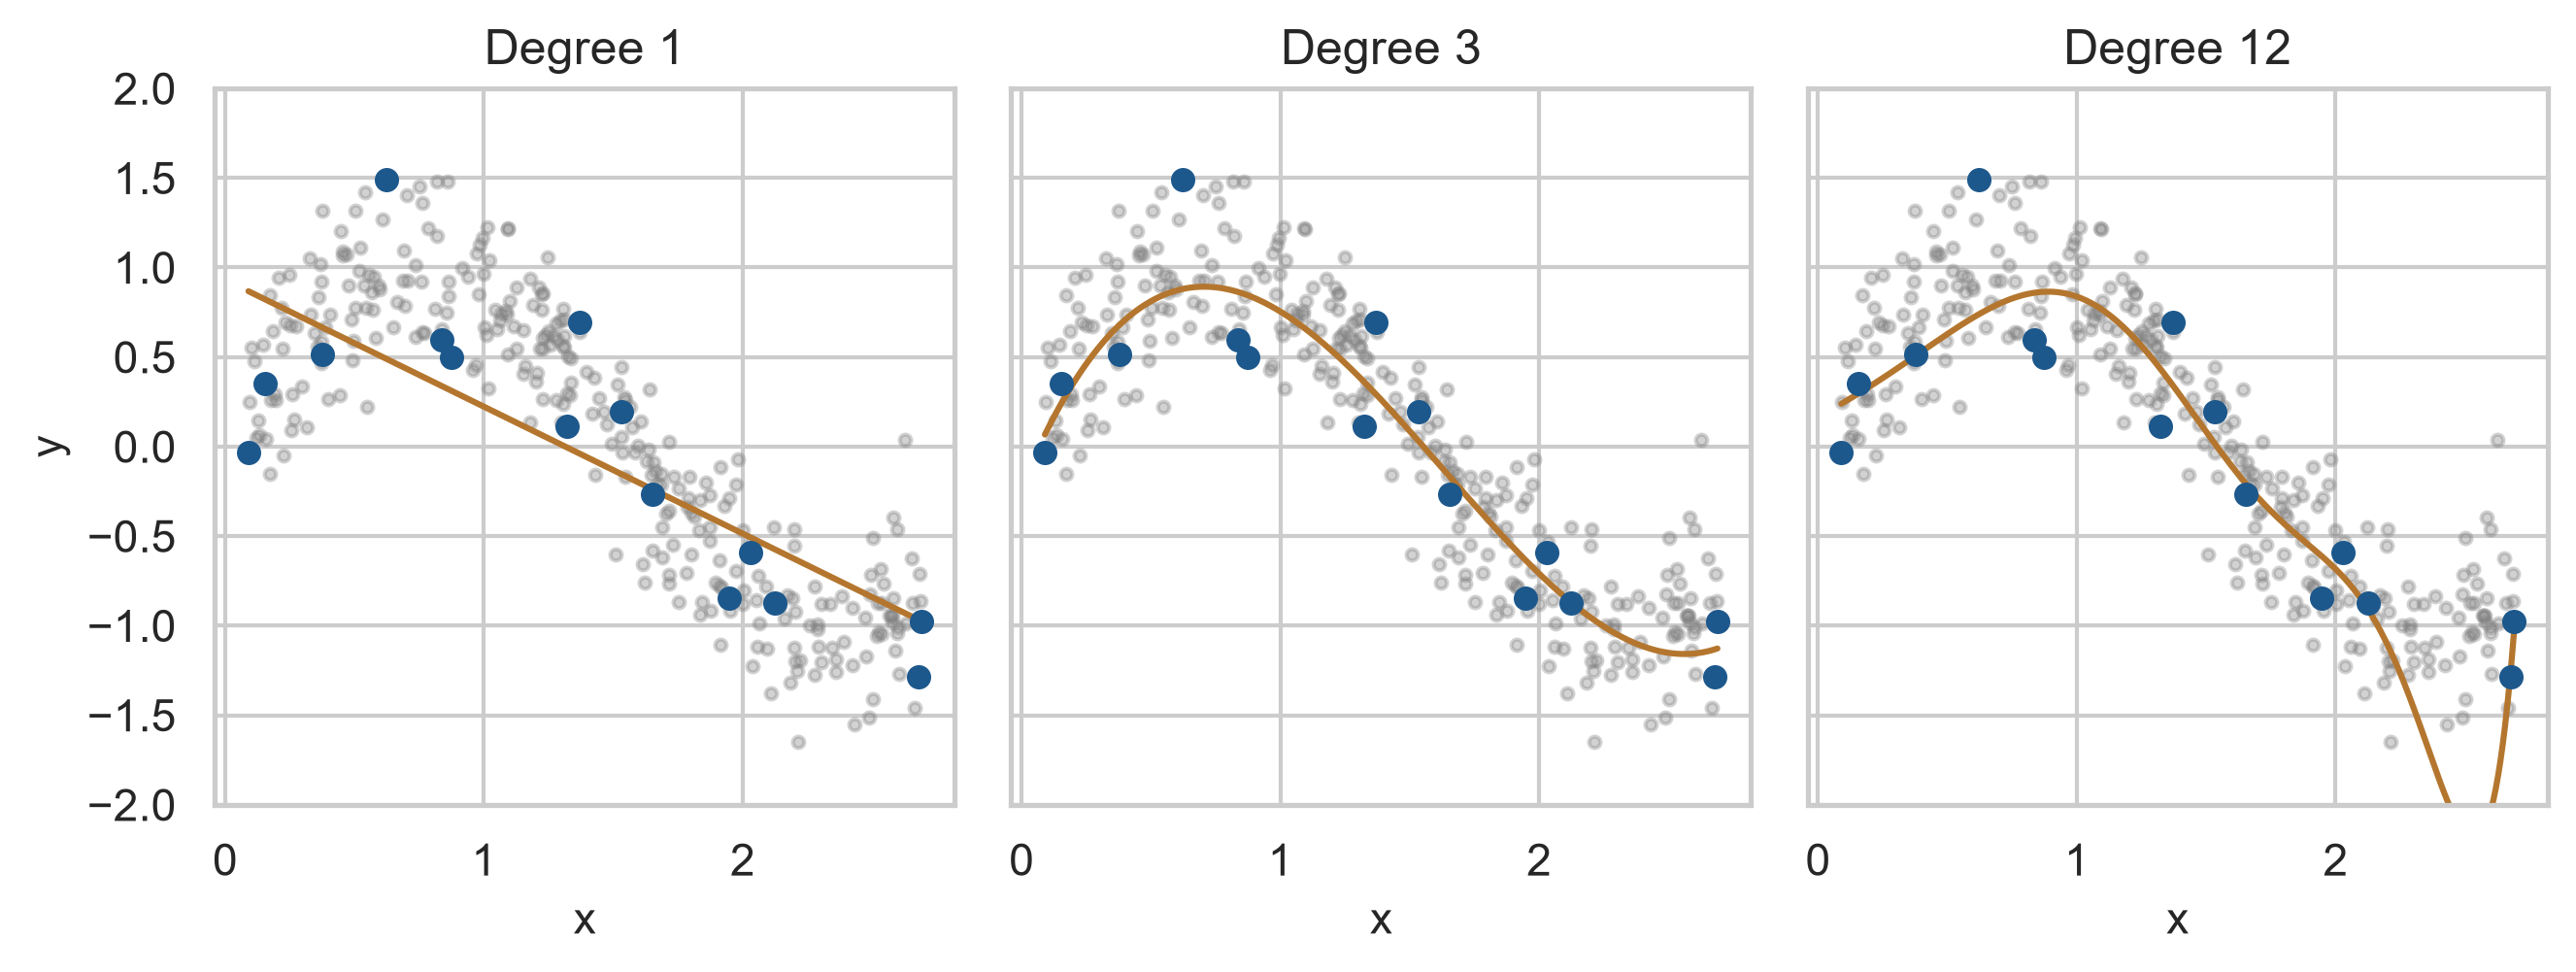
15 noisy points from a wave, and three polynomials of increasing flexibility.
Too simple, about right, too flexible
The line underfits. Degree 3 follows the pattern. Degree 12 threads every training point and swings away from the new ones.
The bias-variance trade-off
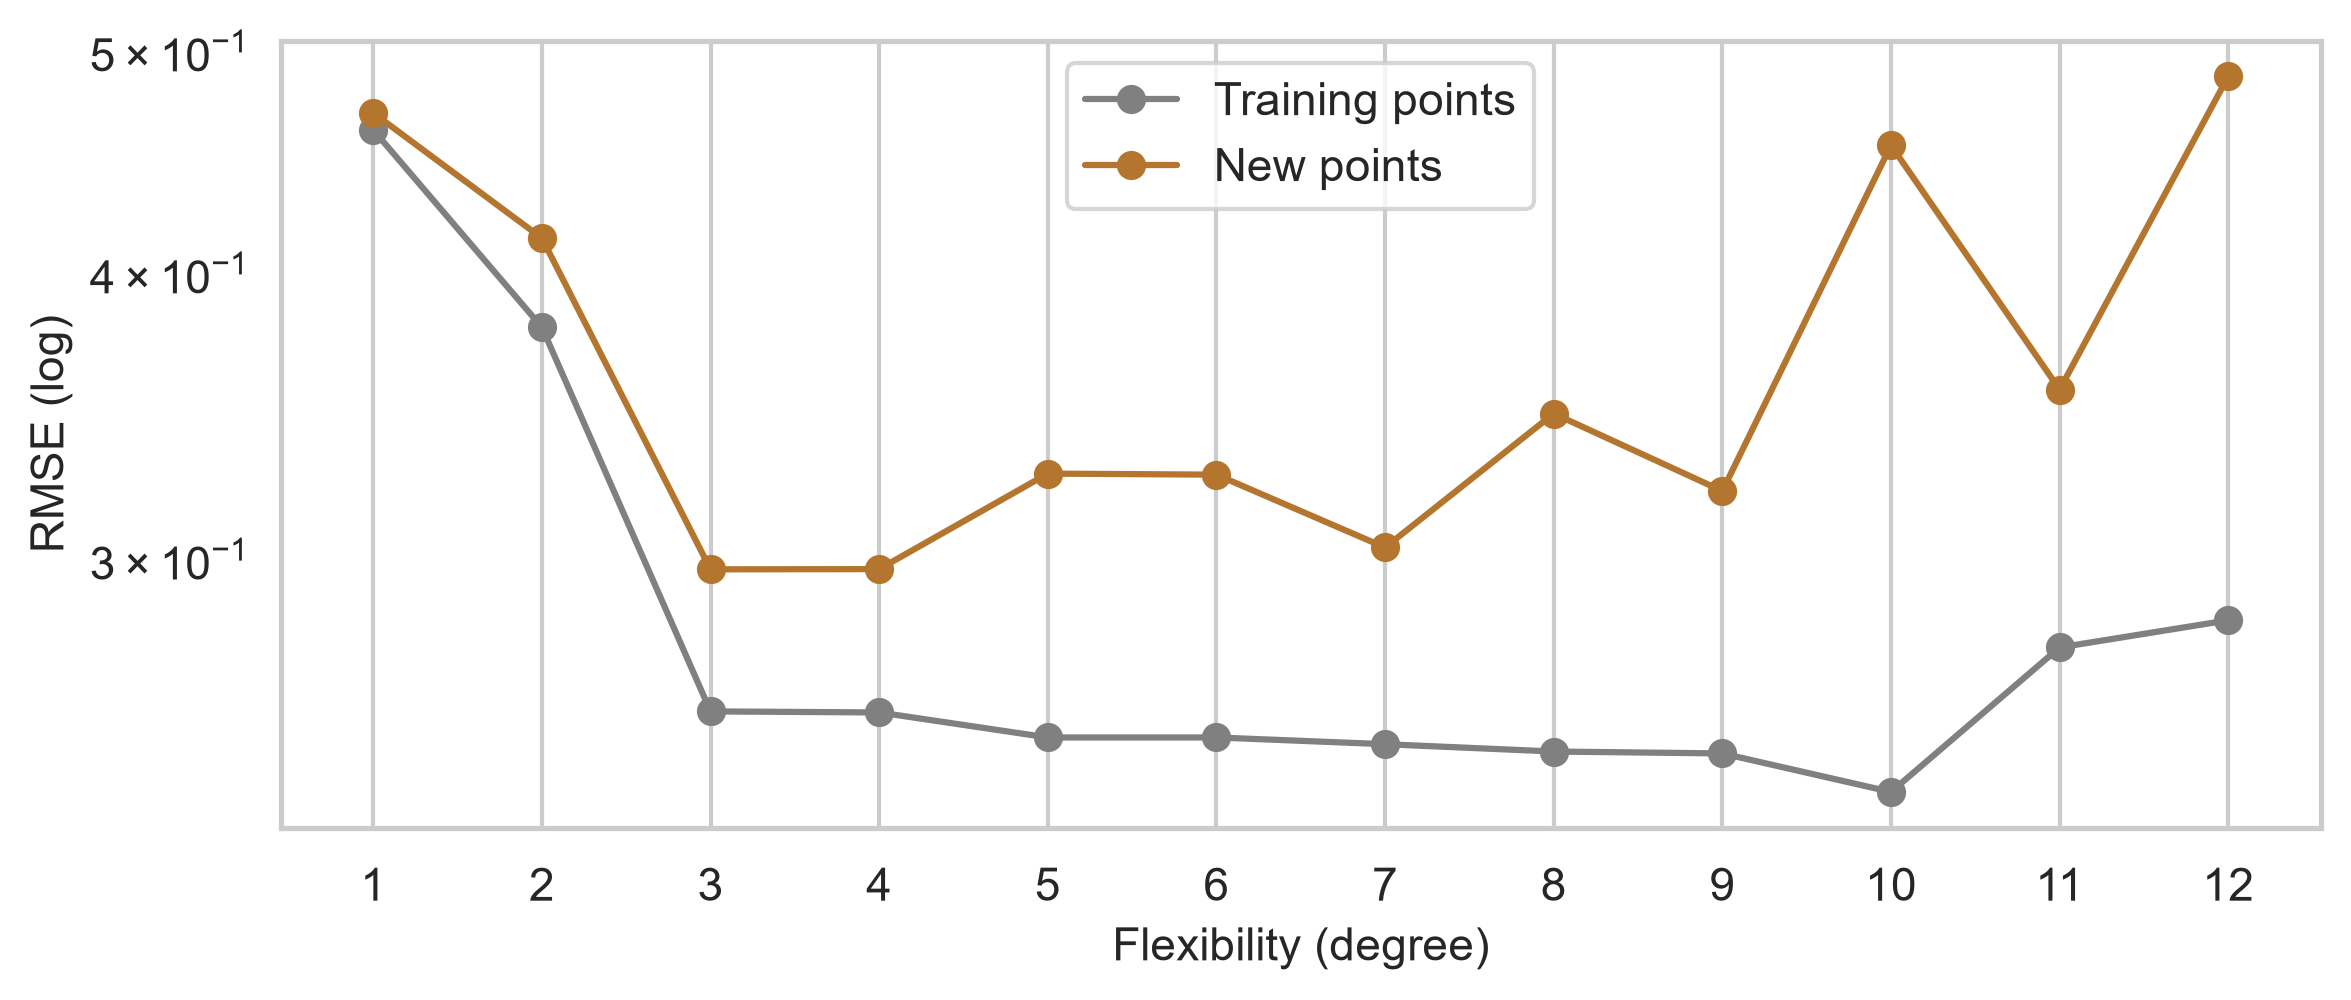
Training error keeps falling. Error on new data is lowest at degree np.int64(3), then rises.
Bias and variance
| Too simple | Too flexible |
|---|---|
| high bias | high variance |
| misses part of the real pattern | follows each sample’s noise |
| wrong whatever the data | changes greatly between samples |
The only way to find the model in between is to measure performance on data it did not learn from.
scikit-learn designs a fair test
| Component | Module | Job |
|---|---|---|
train_test_split |
sklearn.model_selection |
split the data |
ColumnTransformer |
sklearn.compose |
prepare features |
estimators (LogisticRegression) |
sklearn.linear_model |
specify models |
Pipeline |
sklearn.pipeline |
combine preparation & model |
GridSearchCV |
sklearn.model_selection |
tune hyperparameters |
metrics (roc_auc_score) |
sklearn.metrics |
measure performance |
The workflow of a fair test
flowchart TB
  A[All data] --> B[train_test_split]
  B --> C[Training data]
  B --> T[Test data, set aside]
  C --> D[ColumnTransformer] --> E[Fit and tune with<br>cross-validation] --> F[Final model]
  T --> G[Evaluate once]
  F --> G
All choices use the training data. The test data is used once, at the end.
Use only what is known at prediction time
dropout_data = (
    students
    .merge(scores, on="student_id")
    .merge(sem1, on="student_id")
    .drop(columns=["student_id", "supervisor_id", "workshop", "workshop_sessions"])
)
The outcome is binary (\(1\) for “Yes”, \(0\) for “No”), making “Yes” the positive event.
The workshop came after semester 1: using it would be data leakage.
An imbalanced outcome
Only about 15% of students answer “Yes”.
Rare outcomes are common in real prediction, from disease to fraud, and they fool anyone who judges by accuracy alone.
Never judge a model on the data it learned from
X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.25, stratify=y, random_state=2026
)
450 students to train, 150 locked away for the final test.
stratify=y keeps the same share of “Yes” in both partitions.
Preprocessing with ColumnTransformer
preprocessor = ColumnTransformer([
    ("num", Pipeline([
        ("imputer", SimpleImputer(strategy="median")),
        ("scaler", StandardScaler())
    ]), num_cols),
    ("cat", Pipeline([
        ("imputer", SimpleImputer(strategy="most_frequent")),
        ("ohe", OneHotEncoder(drop="first", sparse_output=False, handle_unknown="ignore"))
    ]), cat_cols)
])| Pipeline Step | Job |
|---|---|
SimpleImputer(strategy='median') |
fills missing numbers with the median |
OneHotEncoder(drop='first') |
turns categories into 0/1 dummy columns |
StandardScaler() |
turns numbers into z-scores |
Transforming features
fit() estimates medians, means, and SDs from the training data; transform() applies them.
gender becomes gender_Male; faculty becomes four dummy columns.
No peeking at the test data
The medians, means, and SDs come from the training data only.
They are applied unchanged to the test data.
Calculated from all the data, they would leak test information into the model. Packaging them in a Pipeline prevents this automatically.
Model and pipeline
logistic_pipe = Pipeline([
    ("preprocessor", preprocessor),
    ("classifier", LogisticRegression(max_iter=1000, random_state=2026))
])

logistic_pipe.fit(X_train, y_train)
scikit-learn specifies models with a consistent .fit() and .predict() API.
A Pipeline bundles preprocessing and estimation into a single atomic object.
Predictions on the test students
y_pred_class = logistic_pipe.predict(X_test)
y_pred_prob = logistic_pipe.predict_proba(X_test)[:, 1]

accuracy_score(y_test, y_pred_class)
Accuracy: 88.0%. It sounds good.
Accuracy misleads for rare outcomes
| “Model” | Accuracy | At-risk students found |
|---|---|---|
| logistic regression | 88.0% | some |
| always say “No” | 84.7% | none |
A “model” that ignores every predictor scores as well or better, and helps no one.
ROC AUC
The probability that, of one student who considered dropping out and one who did not, the model ranks the first higher.
| AUC | 0.5 | 1.0 | this model |
|---|---|---|---|
| meaning | coin toss | perfect | 0.84 |
Not fooled by imbalance. Chapter 12 goes further, including decision thresholds.
Overfitting in real data: 1-nearest neighbour
knn1_pipe = Pipeline([
    ("preprocessor", preprocessor),
    ("classifier", KNeighborsClassifier(n_neighbors=1))
])| Data | AUC |
|---|---|
| training | 1.00 |
| test | 0.61 |
On training data each student’s nearest neighbour is themselves. The model memorised; it did not learn.
Comparing models without the test set
Models and settings need comparing during building.
- the training data would reward overfitting;
- the test set would be used up.
Cross-validation reuses the training data.
Cross-validation
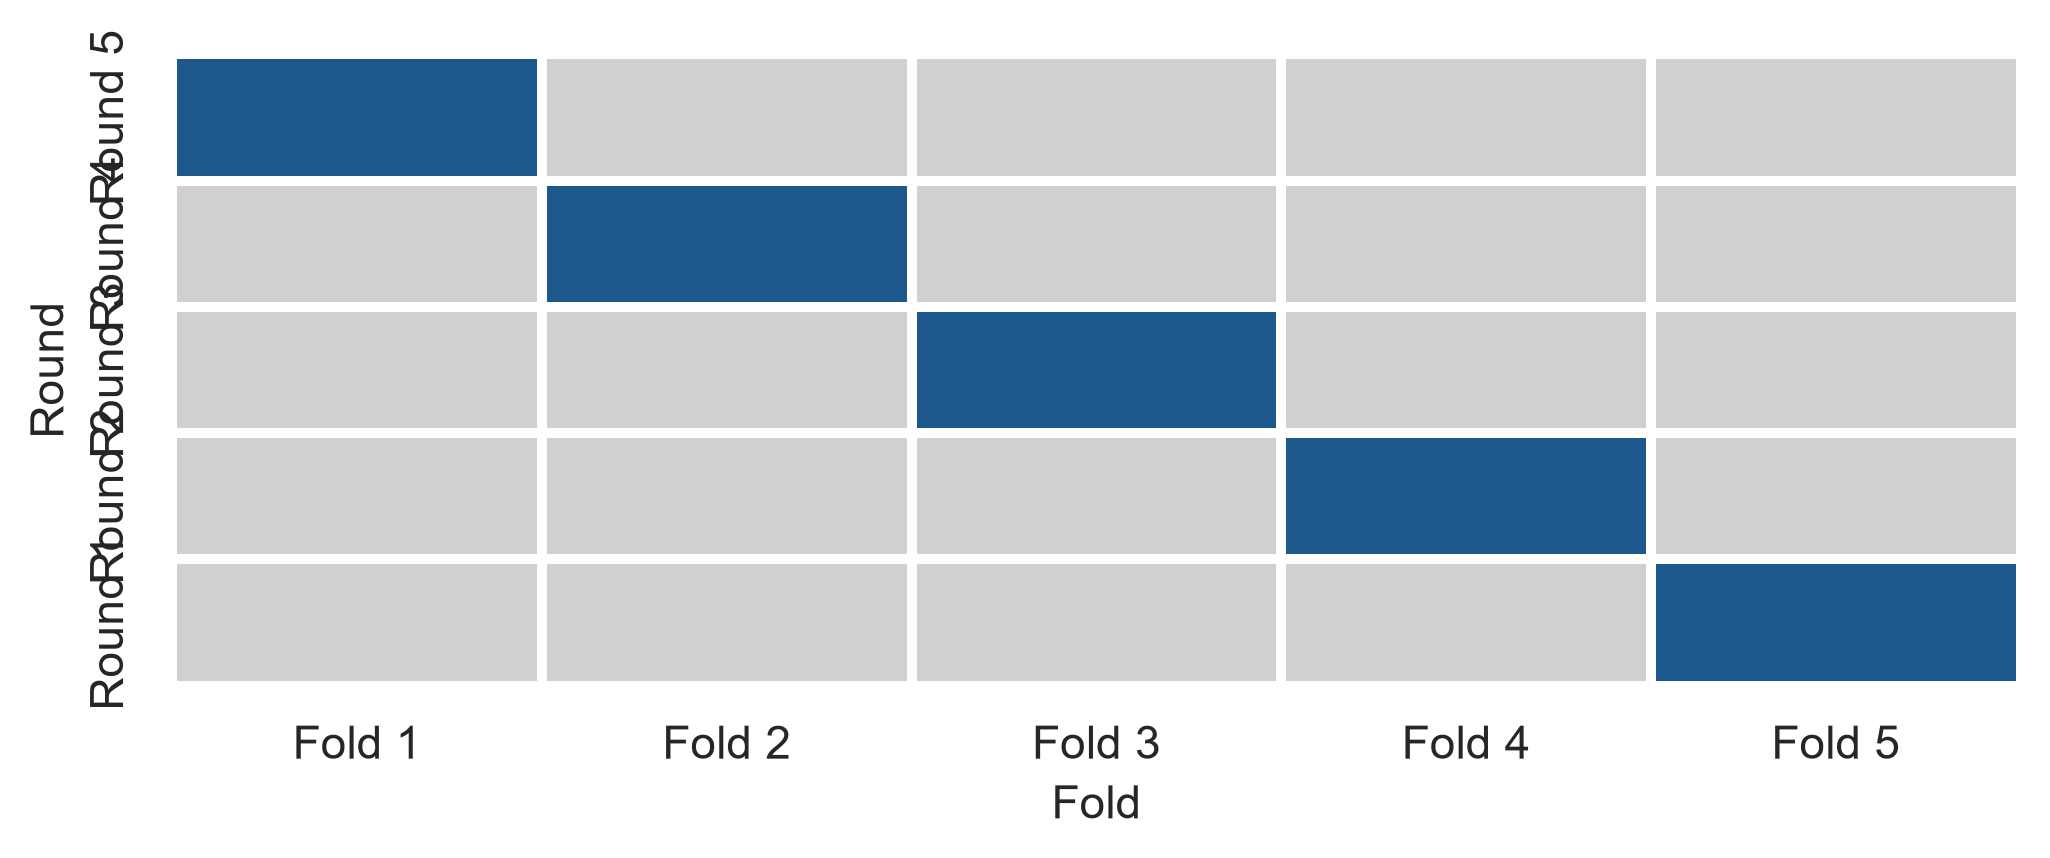
Fit on four folds, evaluate on the fifth, rotate, average. Every student is evaluated once, by a model that never saw them.
Cross-validation with scikit-learn
cv = StratifiedKFold(n_splits=10, shuffle=True, random_state=2026)
cv_res = cross_validate(logistic_pipe, X_train, y_train, cv=cv, scoring=["roc_auc", "accuracy"])
Cross-validated AUC ≈ 0.81 (standard error 0.020): an honest estimate, without touching the test set.
Parameters and hyperparameters
| Learned from data? | Example | |
|---|---|---|
| parameter | yes | regression coefficients |
| hyperparameter | no, chosen beforehand | k in k-NN, tree depth, polynomial degree |
Tuning tries several hyperparameter values and compares them with cross-validation.
Tuning a decision tree’s depth
tree_pipe = Pipeline([
    ("preprocessor", preprocessor),
    ("classifier", DecisionTreeClassifier(random_state=2026, min_samples_leaf=10))
])

grid = GridSearchCV(tree_pipe, param_grid={"classifier__max_depth": range(1, 11)}, cv=cv, scoring="roc_auc")
grid.fit(X_train, y_train)
A tree asks yes-or-no questions in a row. Its depth controls flexibility. GridSearchCV searches the parameter grid.
Depth against AUC
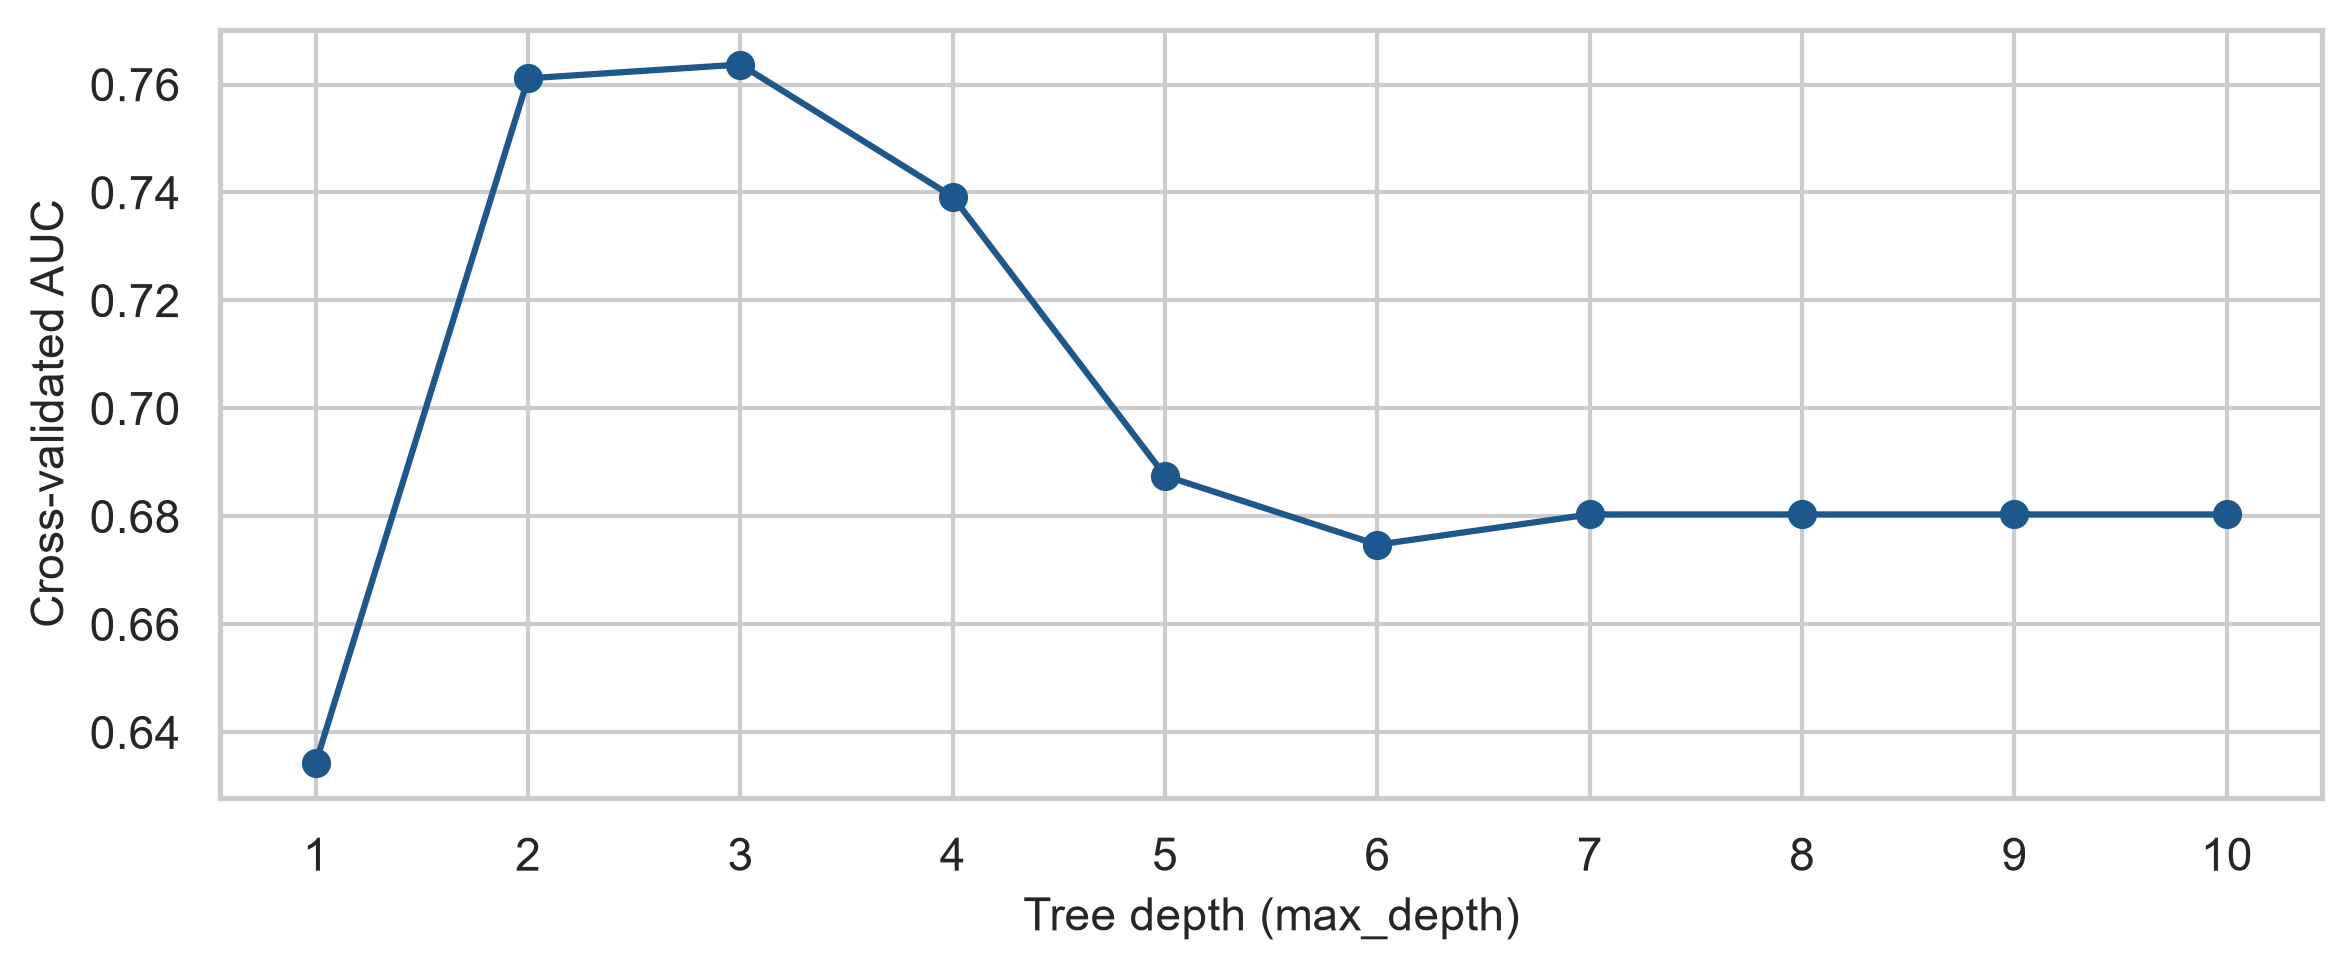
Depth 1 is chance; AUC rises, then levels off and dips as deep trees overfit. best_params_ picks depth 3.
The final test
best_tree = grid_search.best_estimator_
tree_test_auc = roc_auc_score(y_test, best_tree.predict_proba(X_test)[:, 1])
lr_test_auc = roc_auc_score(y_test, logistic_pipe.predict_proba(X_test)[:, 1])
Evaluate once on the held-out test partition.
The simple model wins
| Model | Test AUC |
|---|---|
| tuned decision tree | 0.73 |
| logistic regression | 0.84 |
Dropout risk rises steadily with stress and falls with support: a smooth model captures that; a tree cuts it into boxes.
Try a simple model first, and make a complex one earn its place.
Predictions about people
- a student flagged by mistake may be treated differently;
- a student who is missed receives no help;
- a good overall AUC can hide unfairness to one group;
- the right use here is to offer support earlier, never to penalise.
Check the model separately for women and men, part-time and full-time students.
In your field: business and finance
credit_pipe = Pipeline([
    ("preprocessor", credit_pre),
    ("classifier", LogisticRegression(max_iter=1000, random_state=1))
])
credit_pipe.fit(X_train_c, y_train_c)
Loan applications and whether they turned out well. Only the data changed.
The Brier score measures probability quality: 0 is perfect.
Practical lab: the Chapter 11 playground
Work through the playground exercises in your browser, with hints and solutions.
scikit-learn runs right inside your browser with Pyodide; every exercise also runs locally in VS Code or Jupyter.
Practical exercises 1–3: data and models
- Remove the questionnaire scores: how much does the AUC fall?
- Split 80/20 with another seed: how much does the test AUC move?
- Tune k-NN over 5, 11, 21, 41 neighbours and compare with logistic regression.
Practical exercises 4–6: judgement
- What does
VarianceThreshold()do, and when is it useful? - Explain to an administrator why 85% accuracy may be useless.
- With 50 training points, how does the new-data error curve change?
Try this yourself
Think of a prediction your own field needs.
- what outcome, and when must the prediction be made?
- which variables would be known at that moment?
- how rare is the outcome, and which measure would you use?
- what would the cost of each kind of error be?
Troubleshooting guide (Part 1)
| Symptom | Likely cause |
|---|---|
| a near-perfect training score | overfitting; judge on new data |
| a model better than seems possible | data leakage from the future |
| high accuracy, no cases found | an imbalanced outcome |
| positive class reversed | check binary encoding (1 = positive event) |
Troubleshooting guide (Part 2)
| Symptom | Likely cause |
|---|---|
| test set used to pick the model | it is no longer a test; use cross-validation |
| preprocessing on all the data | test information leaked; use a Pipeline |
| unequal “Yes” shares in train and test | split not stratified (stratify=y) |
| a complex model loses to a simple one | the pattern is smooth; that is fine |
Completion checklist
Misconceptions to leave behind (Part 1)
| Misconception | Better mental model |
|---|---|
| a good training fit predicts well | only new-data performance counts |
| more complex is better | flexibility adds variance |
| high accuracy means a good classifier | not for imbalanced outcomes |
Misconceptions to leave behind (Part 2)
| Misconception | Better mental model |
|---|---|
| the test set can choose between models | choose by cross-validation; test once |
| a good predictor is a cause | prediction needs association only |
The chapter in one sentence
A predictive model is only as good as its performance on data it has never seen, so design the test before you build the model.
Next: Chapter 12
The next chapter compares classifiers:
- decision trees and random forests;
- k-nearest neighbours and support vector machines;
- comparing models fairly;
- the confusion matrix and choosing a threshold;
- imbalanced outcomes and fairness.
Questions
If a model flagged students at risk, who should see the flag?
What would you do for a student it missed?